Measure outcomes, not inventory
The organizations deriving real value from AI are not the ones with the longest agent inventory. They are the ones asking sharper questions about what each agent actually accomplishes. Enterprise leaders need to shift from counting tools to measuring outcomes.
Latest news
 Best Buy Launches Massive DoorBOOster Sale Ahead of Black Friday
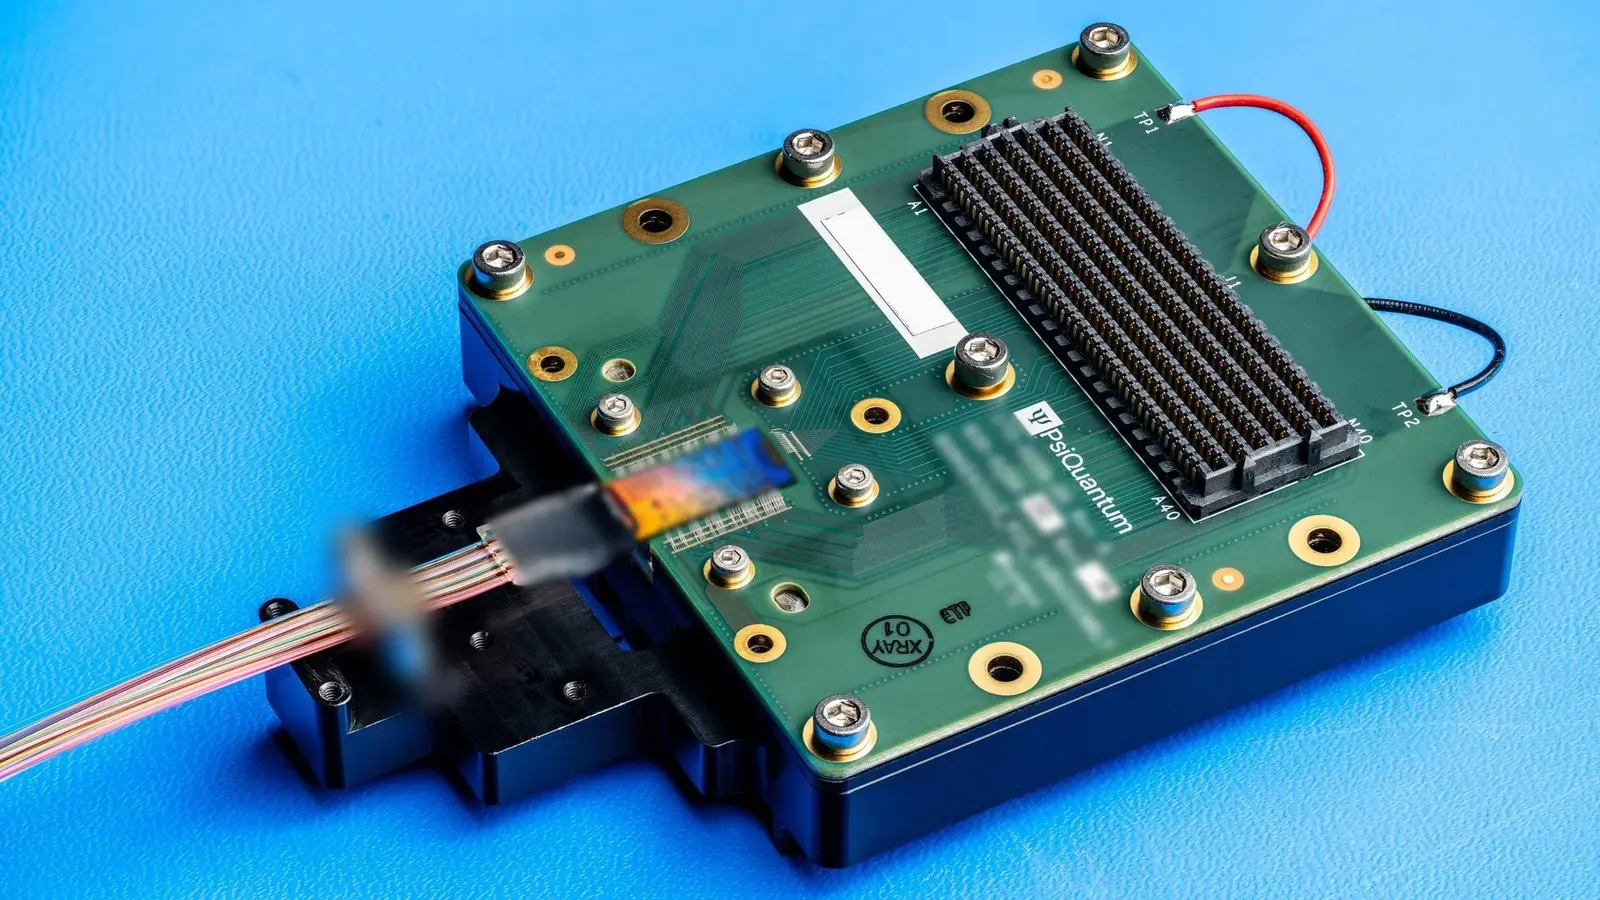 PsiQuantum Unveils Optical Switch for AI Data Centers
 Apple TV 4K Remotes Now Trackable in Find My App
 TCL 27C2A Pro: 27-inch QD-Mini LED 4K gaming monitor delivers extreme color and brightness
Many executives default to a single metric: the number of active agents. It is easy to display on a slide and compare against competitors. However, this metric often masks inefficiency and misaligned priorities.
Senior Vice President for Oracle UK & Ireland, Acre, argues that leaders should ask what each agent delivers. Did it reduce manual work? Did it improve decision speed? Did it cut costs? These questions reveal whether the investment is paying off.
What should leaders ask instead?
A large agent count can create an illusion of progress. Teams may deploy agents for the sake of deployment, not for solving a specific business problem. The real test is whether the agent changes behavior or results.
Instead of „how many agents do we have?”, ask: „What problem does each agent solve?”and „How do we know it is working?”This reframing forces clarity. It also prevents the trap of collecting agents without evaluating their impact.
Organizations that track outcomes can prune underperforming agents and double down on the ones that deliver. This creates a feedback loop that improves ROI.
Frequently Asked Questions
Why is agent count a poor metric? It rewards quantity over quality. A company may have many agents that overlap or underperform, inflating the number without adding value.
What is a better KPI for agentic AI? Track task completion rates, time saved, error reduction, and cost avoidance per agent. These metrics tie directly to business results.
How do you evaluate agent performance? Define success criteria before deployment. After launch, compare actual results against those criteria. Prune or retrain agents that miss the mark.
Comments
Leave a comment